How to Monitor a Business Automation After Launch
09/25/2026
By Team Nevara | Published 25 September 2026
Launching an automation is not the end of the project. It is the point where the system meets changing data, busy staff, unavailable integrations and customer cases that were not present during testing. A workflow can continue to run while quietly producing duplicate records, delaying exceptions or sending technically successful outputs to the wrong place.
Good monitoring answers three different questions: is the technology running, is the complete process reaching the intended outcome, and can the team identify and correct problems before they spread? This guide shows how to create a monitoring plan that a business owner and delivery team can actually operate.
If the workflow is still being designed, start by mapping the business process and testing a controlled pilot. Monitoring should extend the same acceptance criteria used during the pilot rather than introduce a completely new definition of success after launch.
Start with the business outcome
Write down the outcome the automation is meant to improve. An enquiry-routing workflow might aim to create one complete CRM record, assign the right owner and produce a timely first response. A document workflow might aim to collect required evidence, obtain approval and preserve an auditable decision. This outcome becomes the top layer of the monitoring plan.
Do not treat activity as success. A count of processed items only proves that work entered the system. Pair volume with completion, quality and exception measures so a growing queue or falling approval rate is visible.
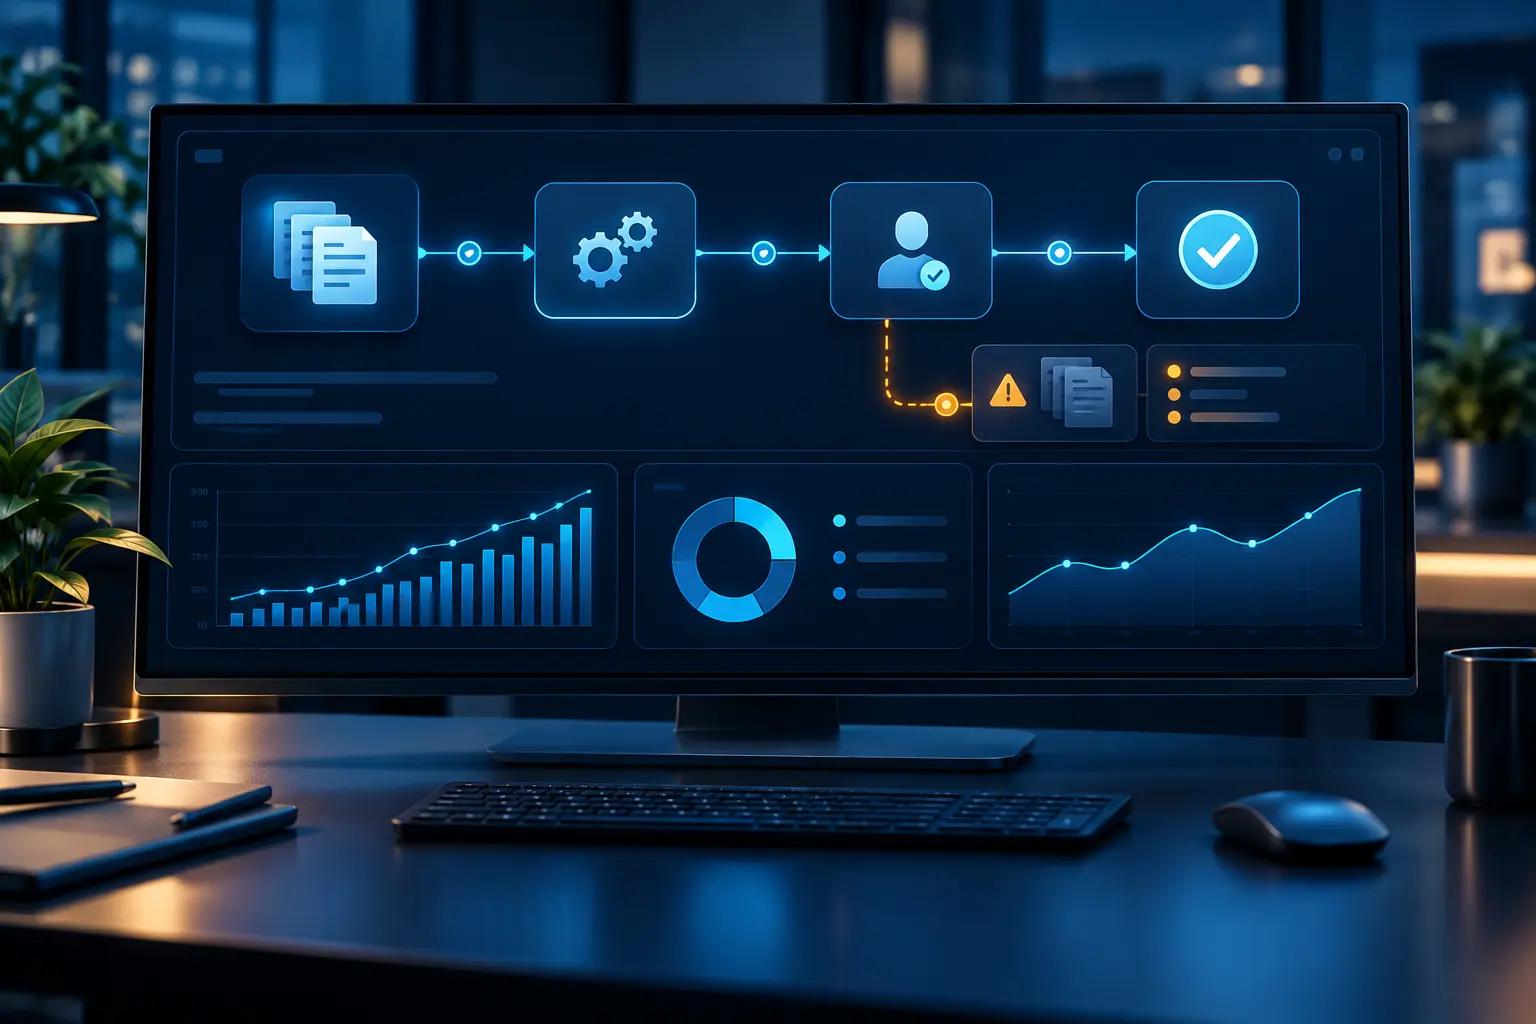
Monitor the workflow in four layers
1. Technical health
Track whether scheduled jobs start, integrations respond, credentials remain valid, queues move and data is stored. Useful signals include failed actions, repeated retries, processing time, unavailable dependencies and records stuck in one state. These measures help the technical owner find faults, but they do not prove the business process worked.
2. Process completion
Follow work from its trigger to its confirmed endpoint. Measure items completed, items waiting, time in each stage, duplicate records and cases that leave the expected path. A payment-confirmation workflow is not complete when an API returns success. It is complete when the correct account and order are updated and the intended recipient receives the right confirmation.
3. Output quality
Sample completed work and record whether staff accept, correct or reject the result. For rules-based automation, review boundary conditions and unexpected combinations. For AI-assisted classification, extraction or drafting, record the type and consequence of corrections instead of relying on one overall accuracy figure. A minor wording edit is different from assigning a sensitive case to the wrong team.
4. Business effect
Compare the live workflow with the baseline recorded before automation. Depending on the process, this might include response time, unresolved work, rework, customer complaints, manual handling time or missed deadlines. Improvements should not be claimed from illustrative examples or a dashboard alone. They need evidence from the real process over a relevant period.
Create an exception queue people can operate
An exception queue is the working list of items the automation could not safely complete. Each item should show what happened, when it happened, which business record is affected, what action is required and who owns the next step. Avoid exposing unnecessary personal or confidential content in alerts and dashboards.
Separate exceptions by urgency. A temporary retry that resolves itself is different from a failed customer commitment, an access-control problem or an incorrect financial update. Set a response target for each class and make ageing visible. A queue without an owner and review routine becomes another inbox that nobody trusts.
Design alerts around action, not noise
Google’s Site Reliability Engineering guidance on monitoring distinguishes between records used for later analysis and urgent notifications that require a person to act. The same principle applies to business automation. Keep useful history in logs and dashboards, but reserve immediate alerts for conditions with a clear owner and response.
Every alert should state the affected workflow, severity, time, business impact, recommended first action and link to the relevant record or runbook. Group repeated failures so one broken integration does not create hundreds of separate notifications. Review alert volume regularly and remove alerts that never lead to action.
Keep an audit trail without collecting everything
The OWASP Logging Cheat Sheet recommends consistent event data and warns against recording sensitive information that should not be stored directly in logs. For each important automation run, retain the identifiers, timestamps, workflow version, status, decision path and human changes needed to investigate an outcome. Mask or exclude secrets, credentials, payment data and unnecessary personal information.
Define how long operational records are retained and who can see them. Logging is a control only if records are accurate, protected and reviewed. Excessive logging can create cost, privacy and security problems without improving decisions.
Monitor AI-assisted steps for change
The NIST AI Risk Management Framework treats risk management as ongoing work across governance, context, measurement and response. In practice, record the model and prompt or configuration version, monitor changes in input patterns, sample outputs and keep a route for people to challenge or correct a result. Re-test when the model, instructions, source data or downstream action changes.
Keep human approval for high-impact outputs unless evidence and governance support a different control. Eligibility, pricing, contractual commitments, sensitive communications and decisions affecting people usually need more than a low error rate in routine cases.
Assign three kinds of ownership
The process owner is accountable for the business outcome and approves changes to the workflow. The operational owner reviews exceptions and confirms that daily work is being completed. The technical owner maintains integrations, credentials, deployments, logs and recovery. One person may hold more than one role in a small business, but the responsibilities should still be named.
Agree who can pause the automation and how staff return to the manual fallback. Test the pause and recovery process before it is needed. The business should not depend on a developer being available to stop a harmful action or recover a queue.
Use a simple review rhythm
Review critical exceptions as they happen, operational measures weekly and business outcomes monthly or at a frequency suited to the process. After any important incident, document the cause, affected records, recovery, control change and evidence that the fix works. Also review the workflow after changes to connected systems, business rules, staff responsibilities or data sources.
Retire measures that no longer help decisions and add new ones only when someone will use them. A concise monitoring view that drives action is more valuable than a large dashboard nobody can interpret.
Illustrative example: monitoring enquiry routing
Consider a fictional professional-services company that routes website enquiries into a CRM. This is an illustrative example, not a Nevara client result. Its dashboard shows new enquiries, records created, duplicate attempts, incomplete cases, assignment time and items waiting for review. Technical alerts cover form failures, expired credentials and CRM errors.
The operations manager reviews the exception queue each morning. A weekly sample checks whether the assigned service and owner were correct. The business owner reviews first-response time and unassigned enquiries monthly against the earlier manual process. If incorrect routing exceeds the agreed tolerance or a critical integration fails, the workflow returns to supervised mode until the cause is fixed and retested.
Frequently asked questions
What should a business automation dashboard show?
Show the intended outcome, completed and waiting work, exceptions by severity and age, processing time, failed actions, quality checks and any business measure used to judge value. Tailor the view to the people making decisions rather than showing every available technical metric.
How often should automation results be reviewed?
Set the frequency according to impact and volume. Critical failures may require immediate response, operational queues may need daily review, and broader outcomes may be meaningful weekly or monthly. Increase review after launch and after material changes, then adjust when evidence supports it.
When should an automation be paused?
Pause when the workflow creates unacceptable customer, financial, privacy, security or operational risk, or when the team cannot verify its outputs. Define these stop conditions before launch and keep a tested manual fallback.
Build monitoring into the automation
Nevara Solutions designs web, app, SaaS and automation systems with operational controls, integrations and measurable workflows. If you are planning a rollout or need visibility into an existing automation, share the process with our team. We can help define the monitoring model, exception handling and improvement plan.
